All projects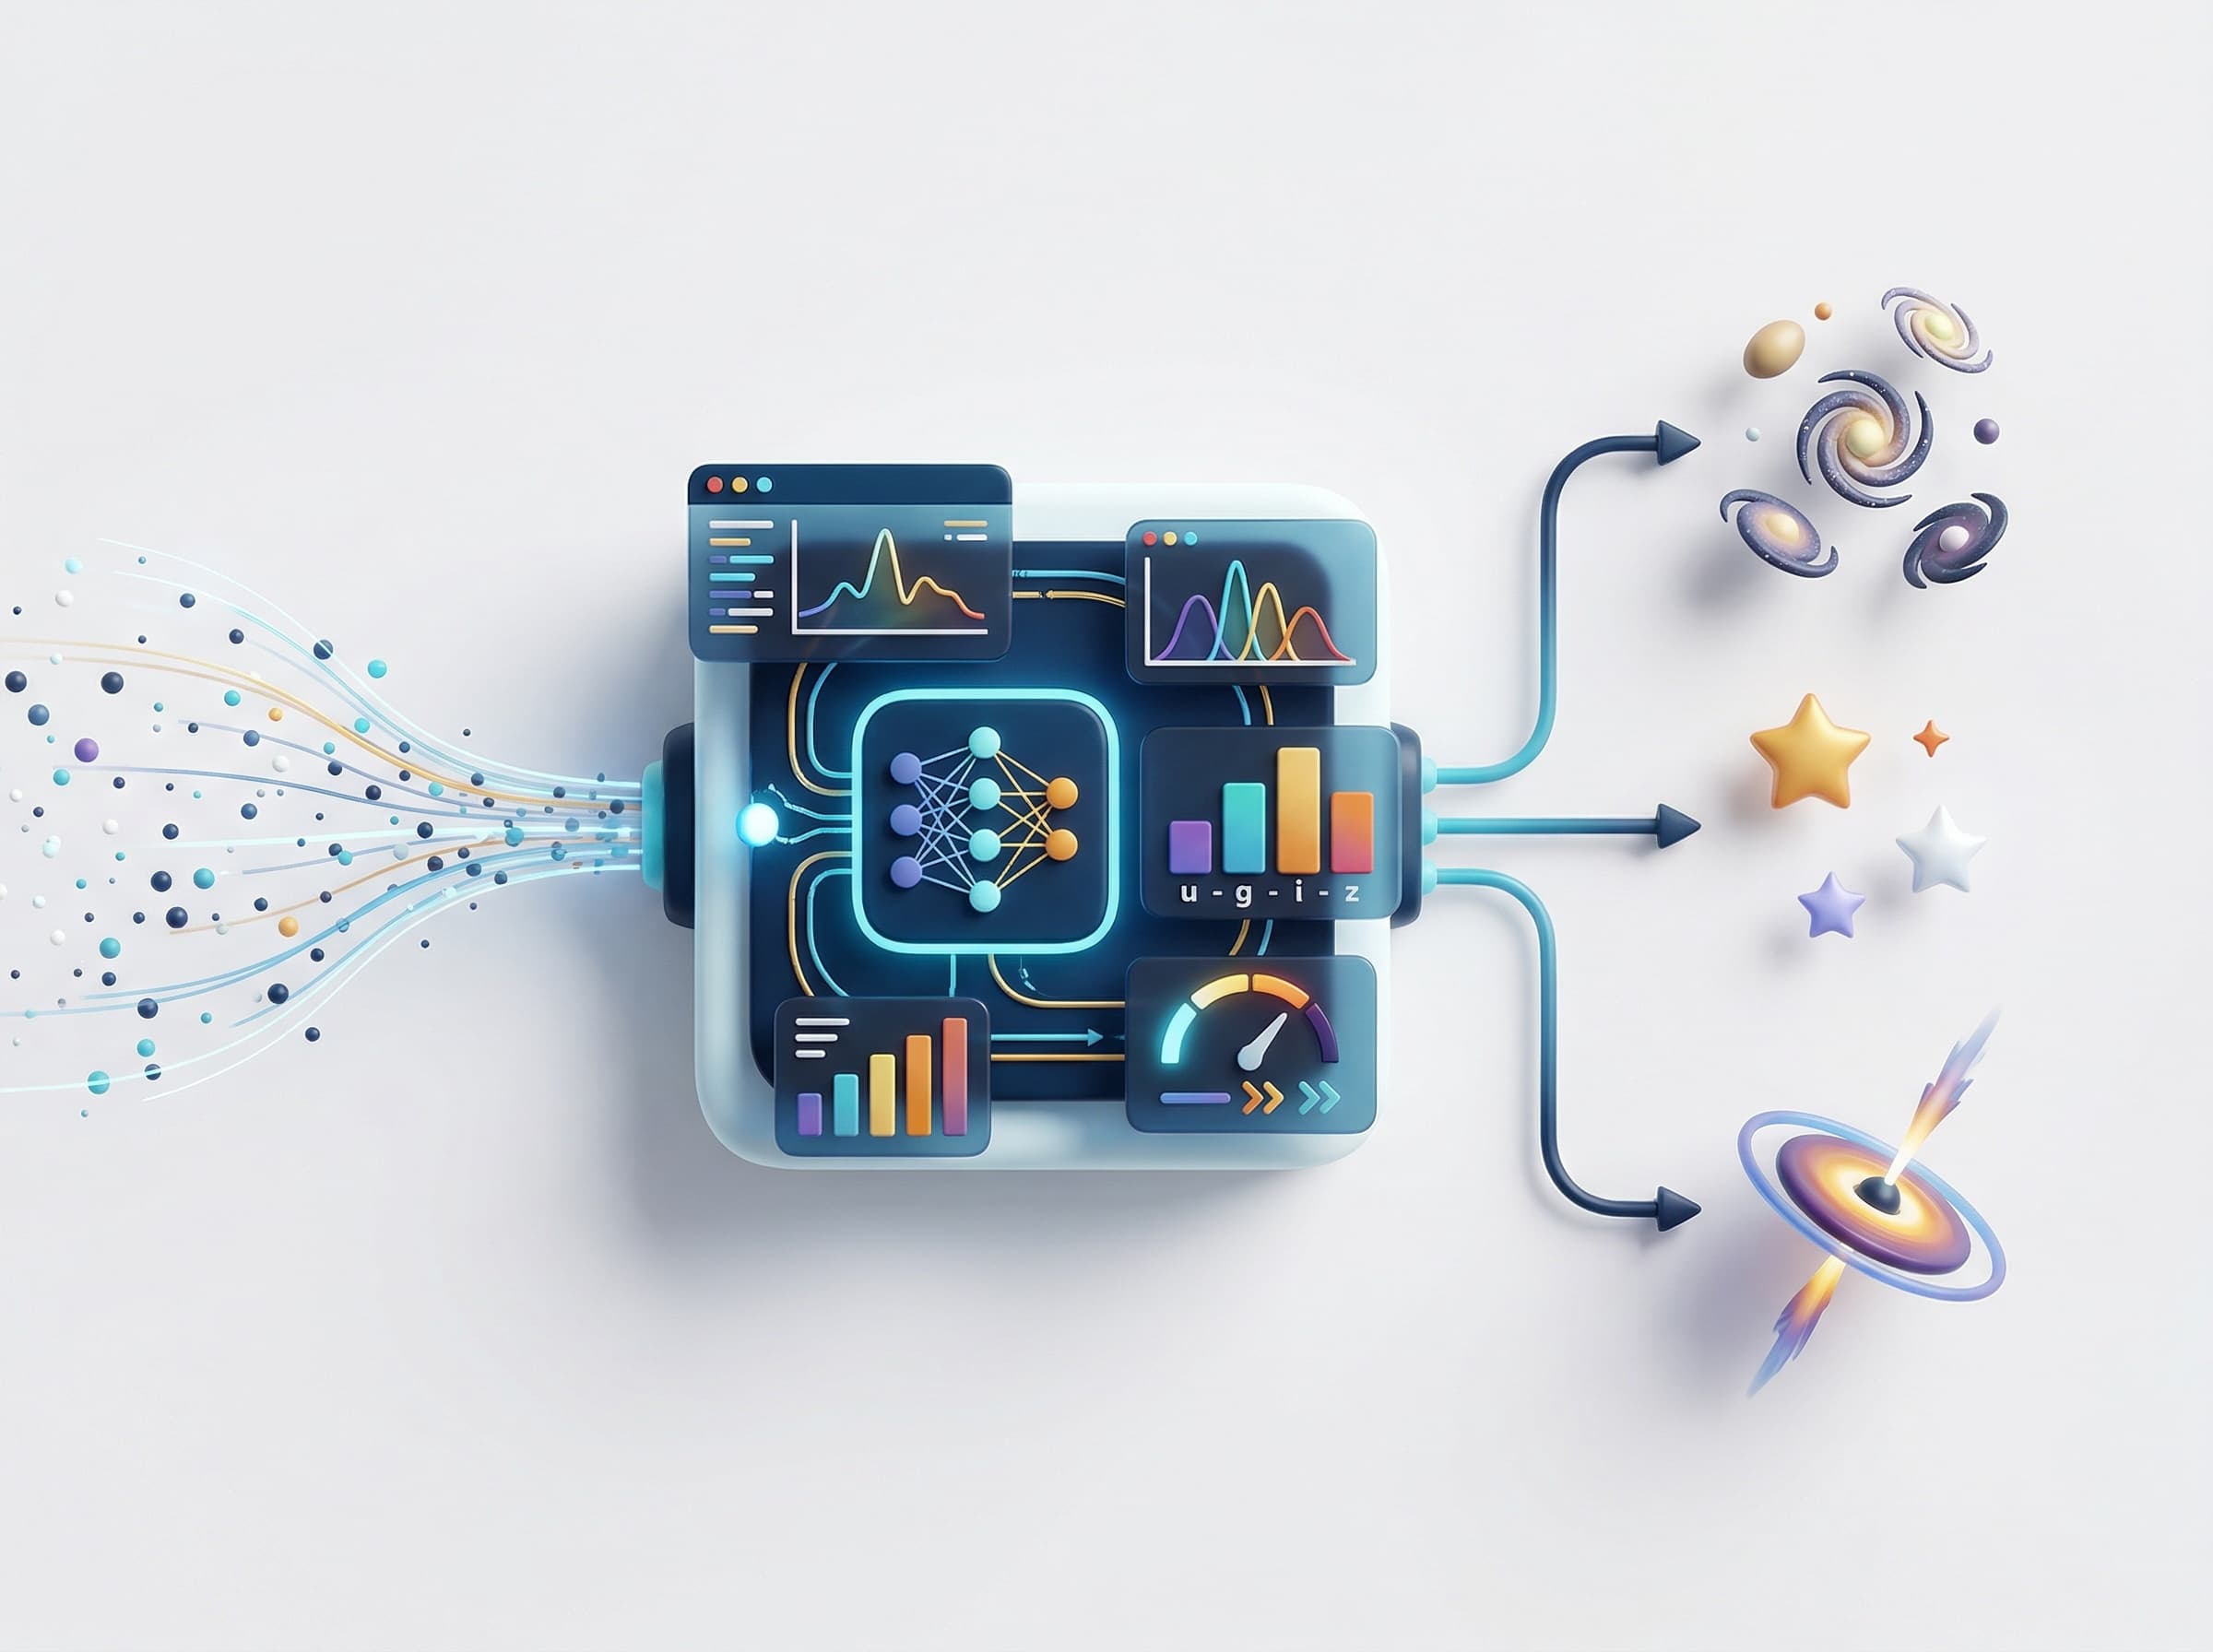
Academic·2026
Stellar Classification
CS372 Machine Learning: An astronomical object classification system
- Role
- AI/ML Engineer
- Team
- Solo Project
- Year
- 2026
Key figures
- 100,000
- SDSS DR17 records
- 3
- Object classes
- 97.85%
- XGBoost accuracy
- 0.9752
- F1-macro
This project was developed to study and apply machine learning techniques to the problem of stellar classification using data from the Sloan Digital Sky Survey (SDSS) Data Release 17 (DR17), consisting of 100,000 records. The system was designed to classify celestial objects into three main categories: galaxies, stars, and quasars. It does this by analyzing spectral features, photometric data across the u, g, r, i, and z filters, and redshift values in order to identify the most accurate and suitable mathematical model for handling large-scale astronomical data.
The problem
- 01Modern astronomy has entered the era of big data, where sky survey projects generate massive amounts of data, often at the terabyte scale per night. Manually classifying these objects is therefore impractical.
- 02Some objects, such as quasars, are high-energy and extremely distant, yet can appear visually similar to stars when observed through conventional telescopes, making them difficult to distinguish.
- 03An automatic classification system is needed to process large volumes of data quickly and accurately, reducing the workload of astronomers and helping identify objects for further in-depth study.
The approach
- 01Performed systematic data cleaning and preprocessing by converting physically invalid sentinel values, such as -9999, into NaN and removing them, while also applying IQR clipping (Winsorization) to reduce the impact of outliers.
- 02Used tree-based methods and permutation importance for feature selection, removing system-identifying variables such as IDs that could lead to data leakage.
- 03Developed and compared three different algorithms: K-Nearest Neighbors (KNN), XGBoost (tree-based ensemble), and a Neural Network (Multilayer Perceptron, or MLP).
- 04Tuned hyperparameters using grid search combined with cross-validation to find the most effective settings while reducing the risk of overfitting and underfitting.
The result
- 01Produced models capable of classifying galaxies, stars, and quasars with very high accuracy, with XGBoost achieving the best performance at an evaluation accuracy of 0.9785 and an F1-macro score of 0.9752.
- 02All developed models showed no significant signs of overfitting and demonstrated strong generalization to unseen data.
- 03Built a complete data pipeline covering preprocessing, anomaly handling, and prediction, which could realistically be applied as an initial screening system within an observatory data pipeline.
Retrospective
Challenges
- The dataset was clearly imbalanced, with galaxies making up nearly 60% of the data while quasars accounted for less than 20%, so macro-averaged F1-score was used as the primary evaluation metric instead of accuracy to prevent model bias.
- Data validation and interpretation required astronomy domain knowledge, such as understanding that certain magnitude values should not be negative and that stellar redshift should remain close to zero. As a result, data cleaning had to be guided not only by statistics but also by physics.
- Managing time and computational resources for running grid search on complex models such as XGBoost and MLP over a large dataset of 100,000 records was a significant challenge.
Learnings
- Gained hands-on experience with the full end-to-end machine learning workflow, including exploratory data analysis, preprocessing, feature engineering, model tuning, and evaluation.
- Learned how different algorithms behave in practice, especially how tree-based models such as XGBoost perform exceptionally well on tabular data and can capture relationships in this type of dataset effectively.
- Understood the importance of handling sentinel values properly, since leaving them untreated can distort averages and data distributions, severely harming model accuracy.
- Learned how to evaluate model performance under class imbalance and compare cross-validation scores with evaluation set results to confirm model reliability.
Interested in work like this?
Tell me about your brief — I reply within 24 hours.